Firecrawl: turning web pages into material for AI
Firecrawl searches for and extracts web content in organized formats. See how it could help research applications and knowledge bases.
Voices depend on your browser and device; some require internet access. Code blocks are not read aloud.
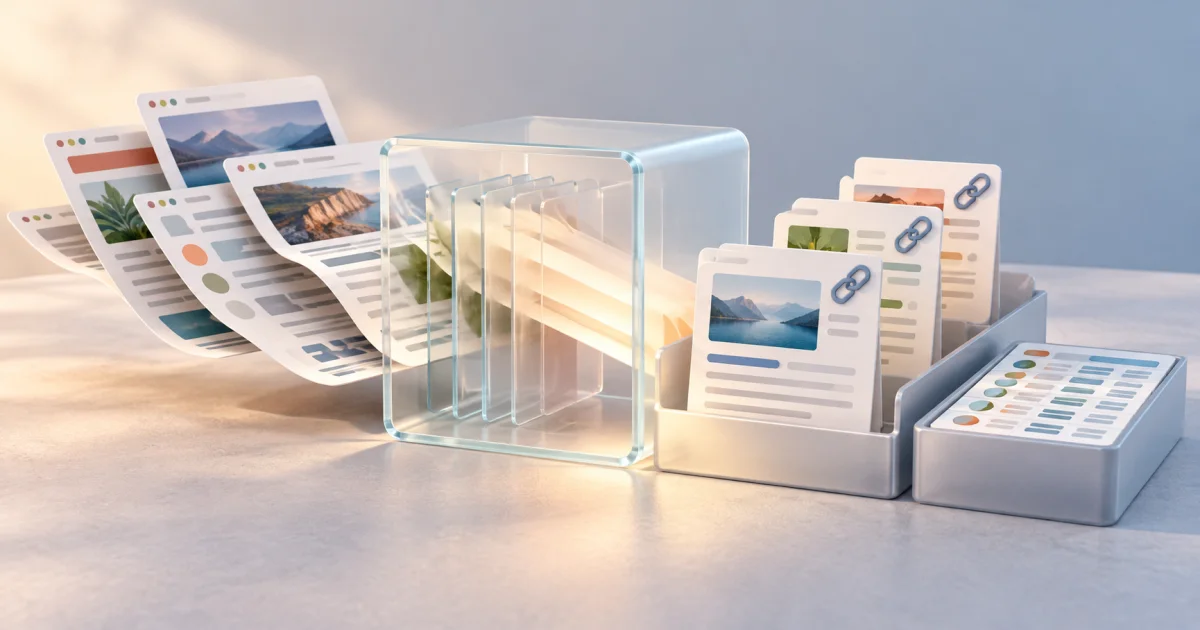
Copying information from a website seems simple until you need to repeat the task across dozens of pages. Menus, footers, and different formats start getting in the way. For an AI application, turning that material into something organized is an important step too. Firecrawl focuses on that part of the process.
The platform offers web search and content extraction through an API. Output formats include Markdown, which preserves an easy-to-work-with text structure, and JSON, which organizes information into fields. Meet Firecrawl.
What does that let you do?
The official documentation describes features for searching for pages, extracting content from specific addresses, finding a site's links, and crawling sets of pages. It also describes ways to interact with pages when a task needs to go beyond the initial reading.
For someone building an application, the appeal is receiving content in a more convenient form to process. The next step might be searching that material, organizing a knowledge base, or producing a summary with references.
An example to move beyond theory
Imagine a company that publishes instructions for using its products across several pages. In a hypothetical project, the team could use Firecrawl to collect that content and feed a knowledge base consulted by a customer support assistant.
This would let the people developing the project devote more attention to how answers will be constructed and less to manually copying each page. They would still need to define which addresses go into the knowledge base, how to handle updates, and how to check the result.
This example illustrates a possible use. The coverage and quality of extraction need to be checked on the sites that actually form part of the project.
Why is it worth following?
I see value in tools that handle the less visible stages of an application. An answer depends on the material that reaches it, so organizing the data deserves the same attention as choosing the AI model.
I would test pages with different formats and compare what was extracted with the original content. Were headings, tables, and important information preserved? Is the text complete? Are the source links still available for verification?
It also makes sense to collect only what is necessary and permitted for the project's purpose. To explore the tool, Firecrawl offers documentation and a testing environment through its official website. Starting with a few pages makes it easier to see where it helps and which adjustments the application still needs.
Official sources consulted on October 21, 2026.