Reducto: AI for turning documents into organized data
Get to know Reducto, a platform that reads documents and extracts structured information to feed systems and AI applications.
Voices depend on your browser and device; some require internet access. Code blocks are not read aloud.
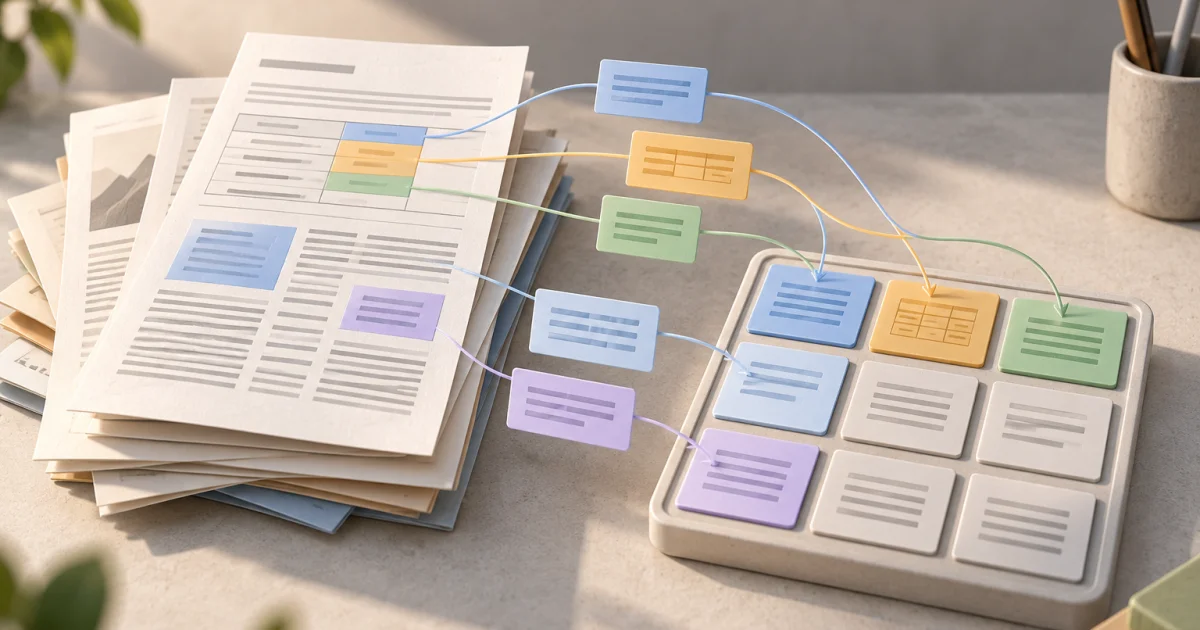
A PDF may look perfectly organized to a reader and still give a system a lot of work. Tables, columns, images, and scanned pages require care to keep each piece of information in the right place. Reducto focuses on this transition from documents to usable data.
The platform offers AI features for interpreting documents, extracting fields, and splitting files into useful sections. In the official overview, the Parse product works with elements such as structure, tables, and formatting. The focus is on teams that need to bring this information into other systems. Explore Reducto.
What does extracting data mean?
Think about the difference between storing an entire document and being able to look up a specific field within it. To automate a process, you often need to know where to find a date, an amount, or an organization's name.
The Extract product lets you define the desired fields in a schema, a kind of template for the result. The response can come in JSON, an organized format that other programs can read. The tool also offers references to the source document so you can check where each piece of information came from.
This is especially interesting for software developers: the output can be prepared in a structure the application already understands, instead of requiring another interpretation of free-form text.
An example to move beyond theory
In an illustrative scenario, imagine a team that receives documents from various suppliers and needs to record the number, date, and total amount for each one. The visual layouts vary, but the fields they are looking for are the same.
The project could define this set of information, process a sample, and compare the results with the original documents. A record without a clear date should be sent for review, following a rule set by the team. This design prevents automation from simply passing an uncertainty on to the next stage.
I would include difficult files in the sample: a poor-quality scan, a table that continues onto the next page, and a document with more than one total. These are the cases that reveal how much checking is needed.
Why follow Reducto?
The offering addresses a fundamental stage for AI applications: preparing information that is trapped in files. A system that answers questions or fills out records depends on the quality of the material it receives.
When exploring the solution, it is worth assessing the accuracy of the fields, how easy it is to check their source, and how the system behaves when information is missing. Cost also needs to be assessed using documents similar to those in the actual operation.
The Extract page provides access to the testing environment and documentation. For teams with many documents to process, Reducto deserves attention for making this stage more structured and verifiable.
Information consulted in official sources on October 21, 2026.