Relace: infrastructure for running AI models through an API
Understand Relace’s current offering as an inference provider for open-weight models and which criteria to assess when integrating it.
Voices depend on your browser and device; some require internet access. Code blocks are not read aloud.
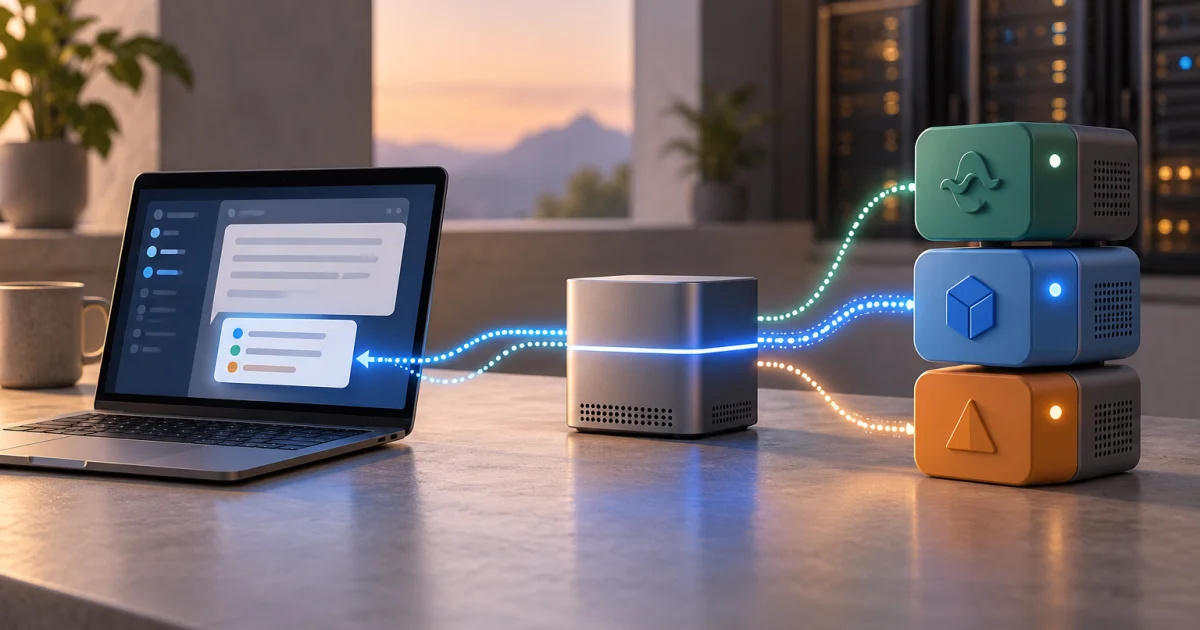
Behind an AI application, there is a very concrete question: where will the model run when someone makes a request? That choice influences speed, cost, and the work needed to keep the service running. Relace comes into the picture on this side of development.
On the official page consulted, the company presents itself as a provider of inference for open-weight models. Let us unpack that: inference is running a model to produce a response. Weights are the parameters learned during its training; when they are available, use remains subject to the terms and license of each model.
The infrastructure behind the answer
The offering lets you access models through an API, an interface programs use to request results. This allows a team to integrate AI capabilities into its product using the infrastructure offered by Relace.
The pricing page states that billing is based on token consumption, with no minimum subscription, and that access is available directly or through OpenRouter. Tokens are units used to process text. Prices vary according to the model and type of usage, so it makes sense to consult the current price table when planning a project.
There is a useful detail for anyone already familiar with the name: the public documentation also describes specialized programming tools, such as searching codebases and applying changes. When assessing the company, it is worth identifying which offering fits your project. Its current main presentation emphasizes inference infrastructure.
How could this be used?
Imagine an illustrative example: a team is developing an application that organizes requests received in writing. It wants to compare models for summarizing each request and suggesting a category.
The evaluation could use a set of fictional messages, with expected responses prepared by the team itself. It would then be possible to compare quality, response time, and cost per request. An inexpensive result that requires a lot of correction may not be the best option for that task.
It would also be useful to test busier periods and define what the application will do when a call fails. This part belongs to product design, even when the model runs on an external service.
Why is it worth following?
Relace stands out for working on the infrastructure that makes it possible to put models into applications. For developers, choosing this provider is part of turning an AI experience into a usable service.
I would start with the availability of the desired model, the terms for data handling, and the cost measured in the actual use case. The official page provides access to registration and commercial information.
The central question is practical: does this service deliver the quality and predictability your application needs? That answer matters more than comparing a promise of speed alone.
Information consulted in official sources on October 21, 2026.