Local AI and Brazil’s LGPD: Controlling Data, Access, and Operations
Hosting the model is one part of the design. Learn to assess data, permissions, isolation, costs, and operations for a local AI deployment with verifiable criteria.
Voices depend on your browser and device; some require internet access. Code blocks are not read aloud.
Estimated reading time: 10 minutes.
“We’ll run the AI on our own server and sort out LGPD compliance.”
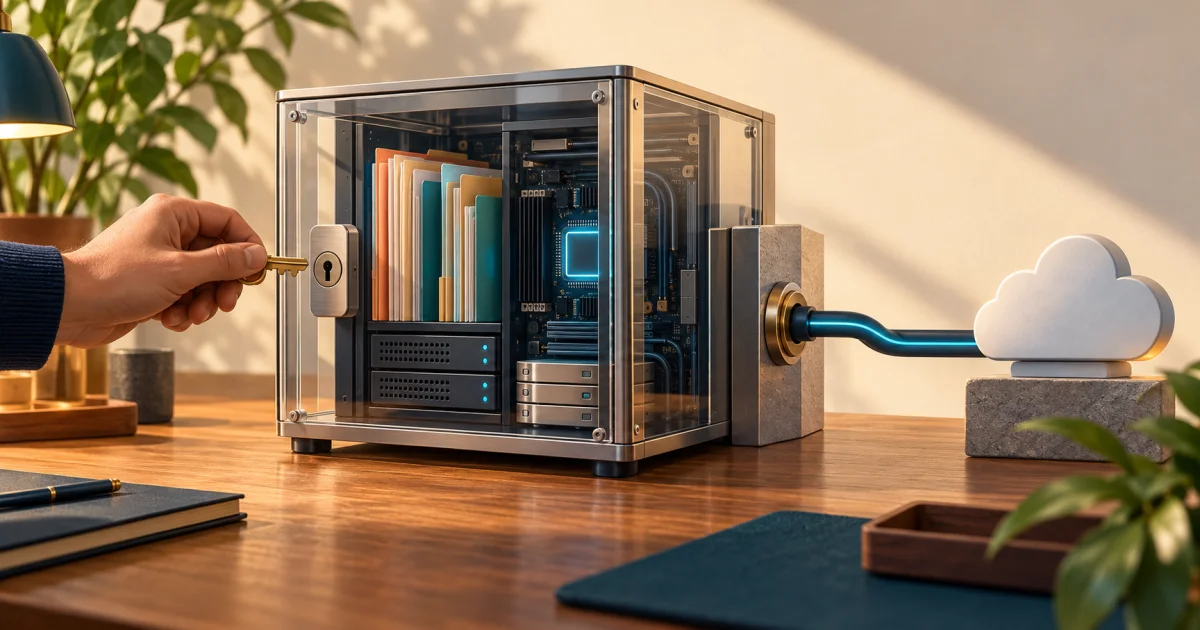
The sentence sounds like a complete plan. In practice, it answers one important question—where to run the model—and leaves several others waiting: who can access the documents, what copies exist, how to delete information, and who keeps everything running.
I like having more control over technology. In my work with integrations and systems, however, I have learned to question solutions that promise to settle an entire discussion with a single infrastructure choice.
A nearby example is the résumé-generator project envisioned for Pinheiral Digital. The intention was to let citizens build a résumé and download the file without retaining their data in the service. That was a design decision, not a claim that the solution had already been deployed or audited.
The initial question was simple: do we need to retain this information to deliver the result? With AI, it is worth starting with the same question before choosing a graphics card.
Local-first, local inference, and sovereignty answer different questions
The local-first concept described by Ink & Switch includes control over data, offline operation, and collaboration. It describes product and storage principles, rather than merely the location where a model performs inference.[1]
An application can keep documents on a device and send them to an API when an AI feature is activated. It can also use a model inside the company while relying on a centralized interface for every other function. Calling something “local” therefore requires finishing the sentence: which part?
To organize that conversation, I would use five questions:
| Dimension | Question we need to answer |
|---|---|
| Inference | Where does the model process the request? |
| Operation | Who manages infrastructure and updates? |
| Data residency | Where are originals, indexes, records, and backups? |
| Control | Who grants access, changes rules, and stops the service? |
| Continuity | How do we recover data and replace components? |
In this project, sovereignty should translate into verifiable capabilities. “We can export the collection” is a more useful answer than an attractive badge saying “sovereign AI.”
What Brazil’s LGPD changes about this decision
Brazil’s LGPD requires purpose limitation, necessity, transparency, and security measures, and provides legal grounds for processing. Article 33 allows international transfers under specified conditions. The law does not impose a general obligation to host all personal data in Brazil.[2]
ANPD Resolution 19/2024 regulates international-transfer mechanisms, including standard contractual clauses and adequacy decisions. The official text notes a 2025 correction. The applicable mechanism depends on the operation; there is no single contractual solution for every situation.[3]
My interpretation for technical design is this: choosing a data center resolves part of the map. The project still needs to justify data use, define access, and demonstrate controls. A team can make mistakes on its own server or build a well-governed external service.
Technical discovery and legal assessment therefore need to work together. A document promising deletion does little good if nobody knows where the backups are. This connects directly with the discussion of Privacy Policies and Terms of Use: the stated conditions need operational support.
Follow a document to the end of its journey
Imagine a company that wants an assistant to answer questions about its own manuals. The initial design looks short: a document goes in, an answer comes out. To assess privacy, I would open that box and record each stage.
The file may need text extraction. Its passages may then produce representations for search, enter an index, become part of a question’s context, and appear in diagnostic records. An answer might also be exported or forwarded to another tool.
These are architectural possibilities, not mandatory stages in every system. The work is to discover which ones actually exist in the chosen deployment.
| Stage | Decision to document |
|---|---|
| Intake | Which files are accepted, and from whom? |
| Extraction | Is content processed locally or sent to a service? |
| Indexing | Which passages enter the index, with which permissions? |
| Query | How is the user identified before retrieval? |
| Logging | Does the log need full content or only metadata? |
| End of use | How are originals, derivatives, and planned copies deleted? |
This table tends to produce better questions than “Which model is more private?” It also reveals an opportunity to simplify: some information may never need to enter the system.
Local tools still require deliberate configuration
The Ollama FAQ distinguishes local execution from cloud models and documents disabling cloud features through the OLLAMA_NO_CLOUD option. You therefore need to check the mode being used, even when the interface is installed on your own computer.[4]
A component’s configuration does not automatically describe the rest of the application. If you add external document extraction or hosted observability, those paths need assessment too. The relevant test follows the entire flow.
Andrej Karpathy’s nanochat is presented as an experimental harness for LLM training, covering stages such as tokenization, training, evaluation, and inference. That purpose does not amount to a ready-made enterprise platform.[5]
It is an interesting resource for understanding mechanisms and experimenting. A customer deployment still needs specifications for operations, identity, availability, and data protection. “The repository runs” is an excellent learning milestone; the service agreement will ask for more.
Sharing a GPU requires thinking about access boundaries
The vLLM security documentation warns that a shared process does not provide isolation between mutually untrusted tenants. It also explains that cache_salt should not be treated as a security boundary.[6]
That matters when someone proposes serving several companies through the same service. The decision needs to consider the isolation each case requires, alongside available memory and speed.
Imagine two fictional customers: Blue Workshop and Green Workshop. Each has different internal documents. Acceptance criteria should require that a Blue user cannot retrieve Green’s content, see it in logs, or receive it in answers.
I would start by separating identity and authorization from the model’s decision. The system determines which documents a user may access before assembling the context. Asking the AI to “remember not to show another customer’s information” leaves protection dependent on interpretation.
Depending on the risk, the architecture may require separate instances or environments. The final design needs to justify its boundaries and test them. Saving the cost of one machine cannot, by definition, justify every level of sharing.
A proof of concept that can say “no”
For an initial experiment, I would use 20 to 30 synthetic documents: invented manuals, fictional procedures, and information created specifically for testing. Real medical records, contracts, or municipal case files should not become improvised laboratory material.
I would define two roles. One can consult general procedures; the other also has access to restricted documents. Each question would have an expected outcome: answer with a source, ask for clarification, or decline because information or access is missing.
The set would include questions with known answers, questions about absent information, and attempts to consult the other role’s material. I would also test an updated document: does the assistant use the new version? Does old content still appear anywhere?
The evaluation would record five elements: answer correctness, cited source, permission enforcement, response time, and cost per accepted task. Criteria need to be defined before comparing models, to avoid picking a favorite and inventing the justification afterward.
A demonstration that can refuse an unauthorized request may be more convincing to a customer than one that answers everything fluently. Trust is also built at the boundaries.
The real cost continues after the download
Downloading model weights may be only the first item on the bill. To compare alternatives, I propose estimating the complete monthly cost:
infrastructure + energy + operations + updates + observability + recovery + engineering time.
Then relate that total to the number of tasks completed at acceptable quality. Include low-demand periods, growth, failures, and support needs. The calculation is a decision model; the values must come from the operation being studied.
A managed API may suit irregular demand and a small team. Running your own deployment may make sense when requirements and volume justify the additional responsibility. These are scenarios to compare, not universal recommendations.
Also check the licenses of the model and its components before offering the service. Access to weights alone does not answer every question about commercial-use conditions.
For people working with SaaS, as I do with Oombe, the useful question is how much it costs to deliver the result sustainably. The cheapest server in the initial quote may require an operation the team cannot yet maintain.
What needs to be agreed before delivery
I would organize deployment around small, verifiable decisions:
- Scope: which tasks the assistant handles and which remain outside it.
- Data: which categories enter, why they enter, and which can be reduced.
- Access: who queries, administers, exports, and reviews permissions.
- Lifecycle: when to update, delete, and review copies.
- Operations: who owns failures, capacity, and updates.
- Evidence: which tests, records, and documents demonstrate the agreement.
Each decision needs an owner. “The team takes care of that” sounds sufficient until an outage leaves nobody sure who can act.
For a small company, this record can start lean. Its quality comes from being usable, updateable, and testable. Adding complexity without a concrete need only creates more moving parts to maintain.
A service opportunity with an honest promise
This work can become an assessment, a proof of concept, an implementation, and continuing support. Deliverables may include a data-flow map, acceptance criteria, a comparison of alternatives, and an operations plan.
When offering that work, I prefer a verifiable promise: “We will demonstrate how the system controls access and meets the defined requirements.” Phrases such as “install it and become compliant” conceal work that still needs to happen.
The same reasoning applies to healthcare and legal services. A proposed use needs a specific assessment; the sector’s name does not authorize assumptions about architecture or financial returns.
My starting point remains the question from the résumé generator: what do we actually need to process and retain? The model, the hardware, and the operating approach follow.
Having control over AI means being able to explain its behavior, enforce limits, and sustain operations. Server location has an important role in that story. It works best when accompanied by the rest of the design.
Sources and further reading
- Ink & Switch — Local-first software, 2019.
- Presidency of Brazil — General Personal Data Protection Law.
- ANPD — Resolution 19/2024.
- Ollama — official FAQ.
- Andrej Karpathy — nanochat.
- vLLM — security documentation.
Sources consulted on October 26, 2026. The evaluation examples are proposed experiments; no deployment results are attributed to the author.